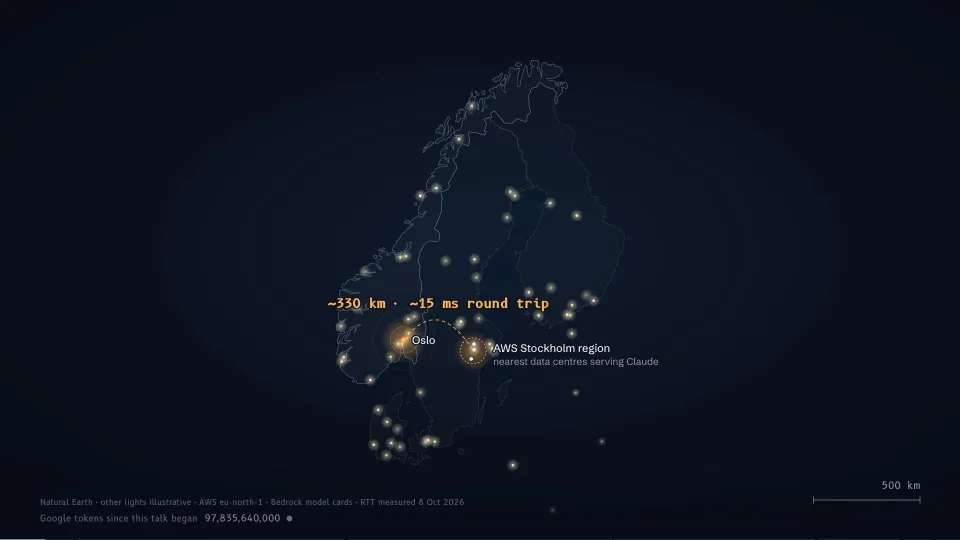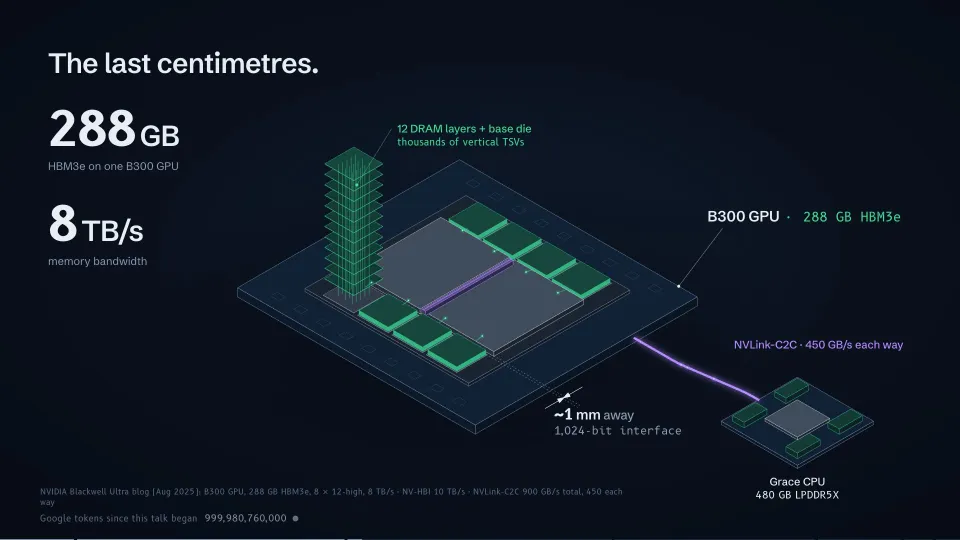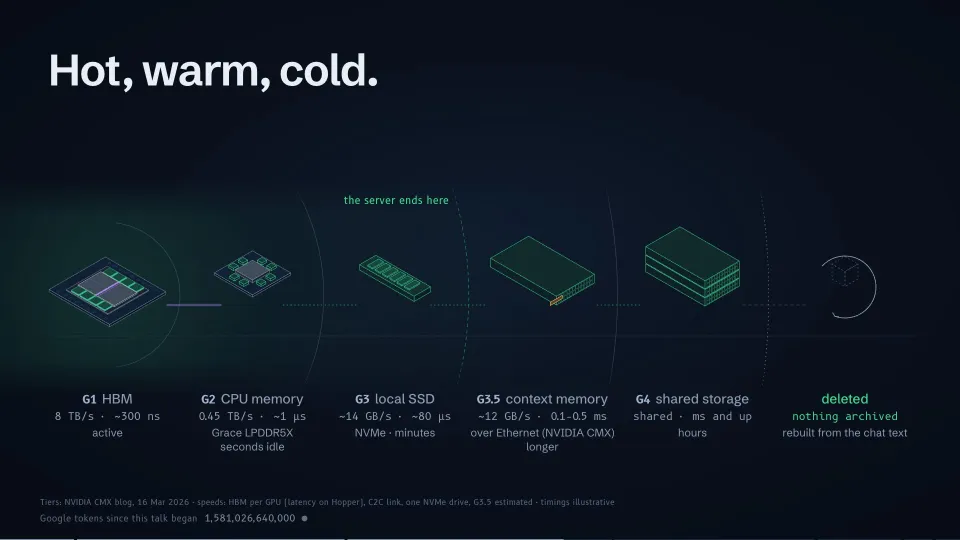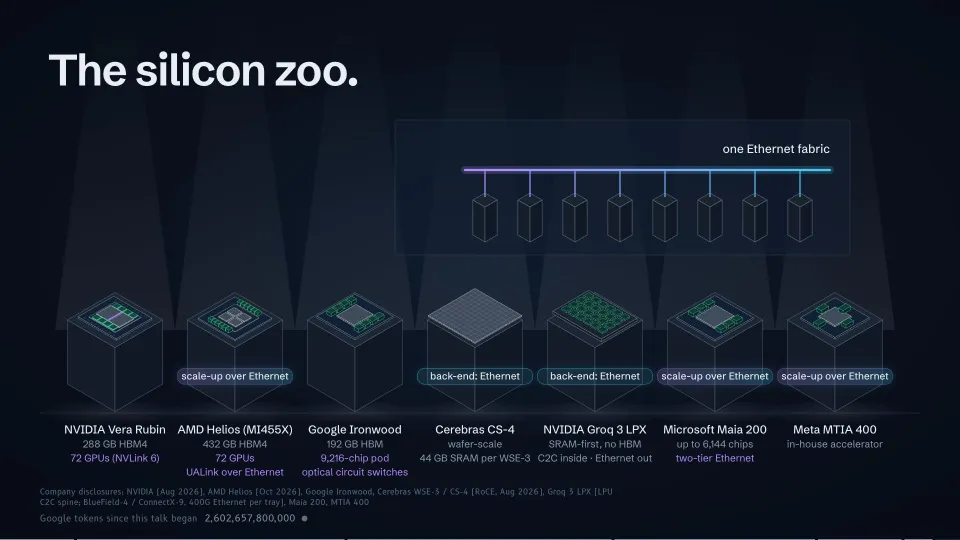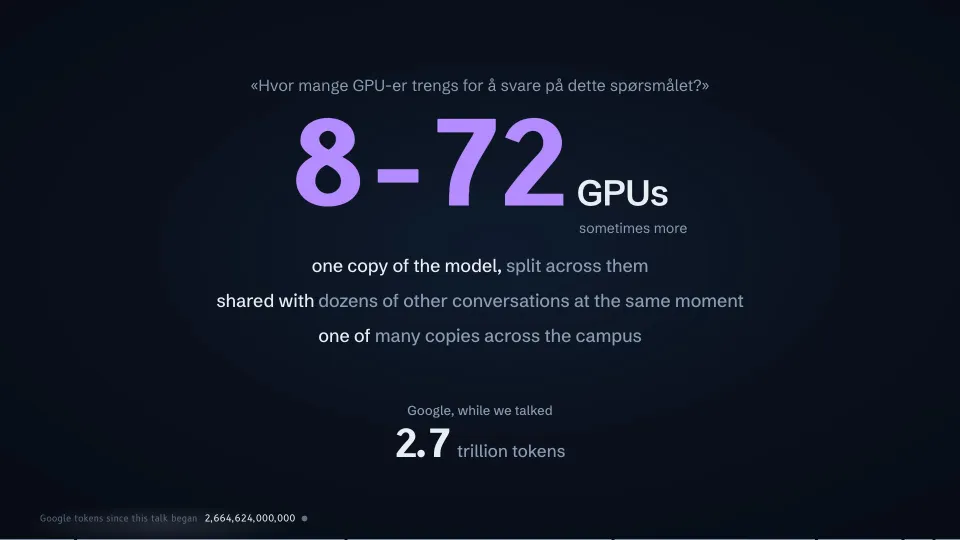
What actually happens in the network when you ask an AI assistant a question? This talk follows one question from a phone in Oslo to a GPU rack in the Stockholm region and back: the front-end, the back-end, scale-up and scale-across, memory tiers, the KV cache, and why inference has become a network problem.
48 minutes, 32 parts.
Outline
- One question
- Pull back
- Power north, people south
- Leaving Oslo
- The front door
- The front-end
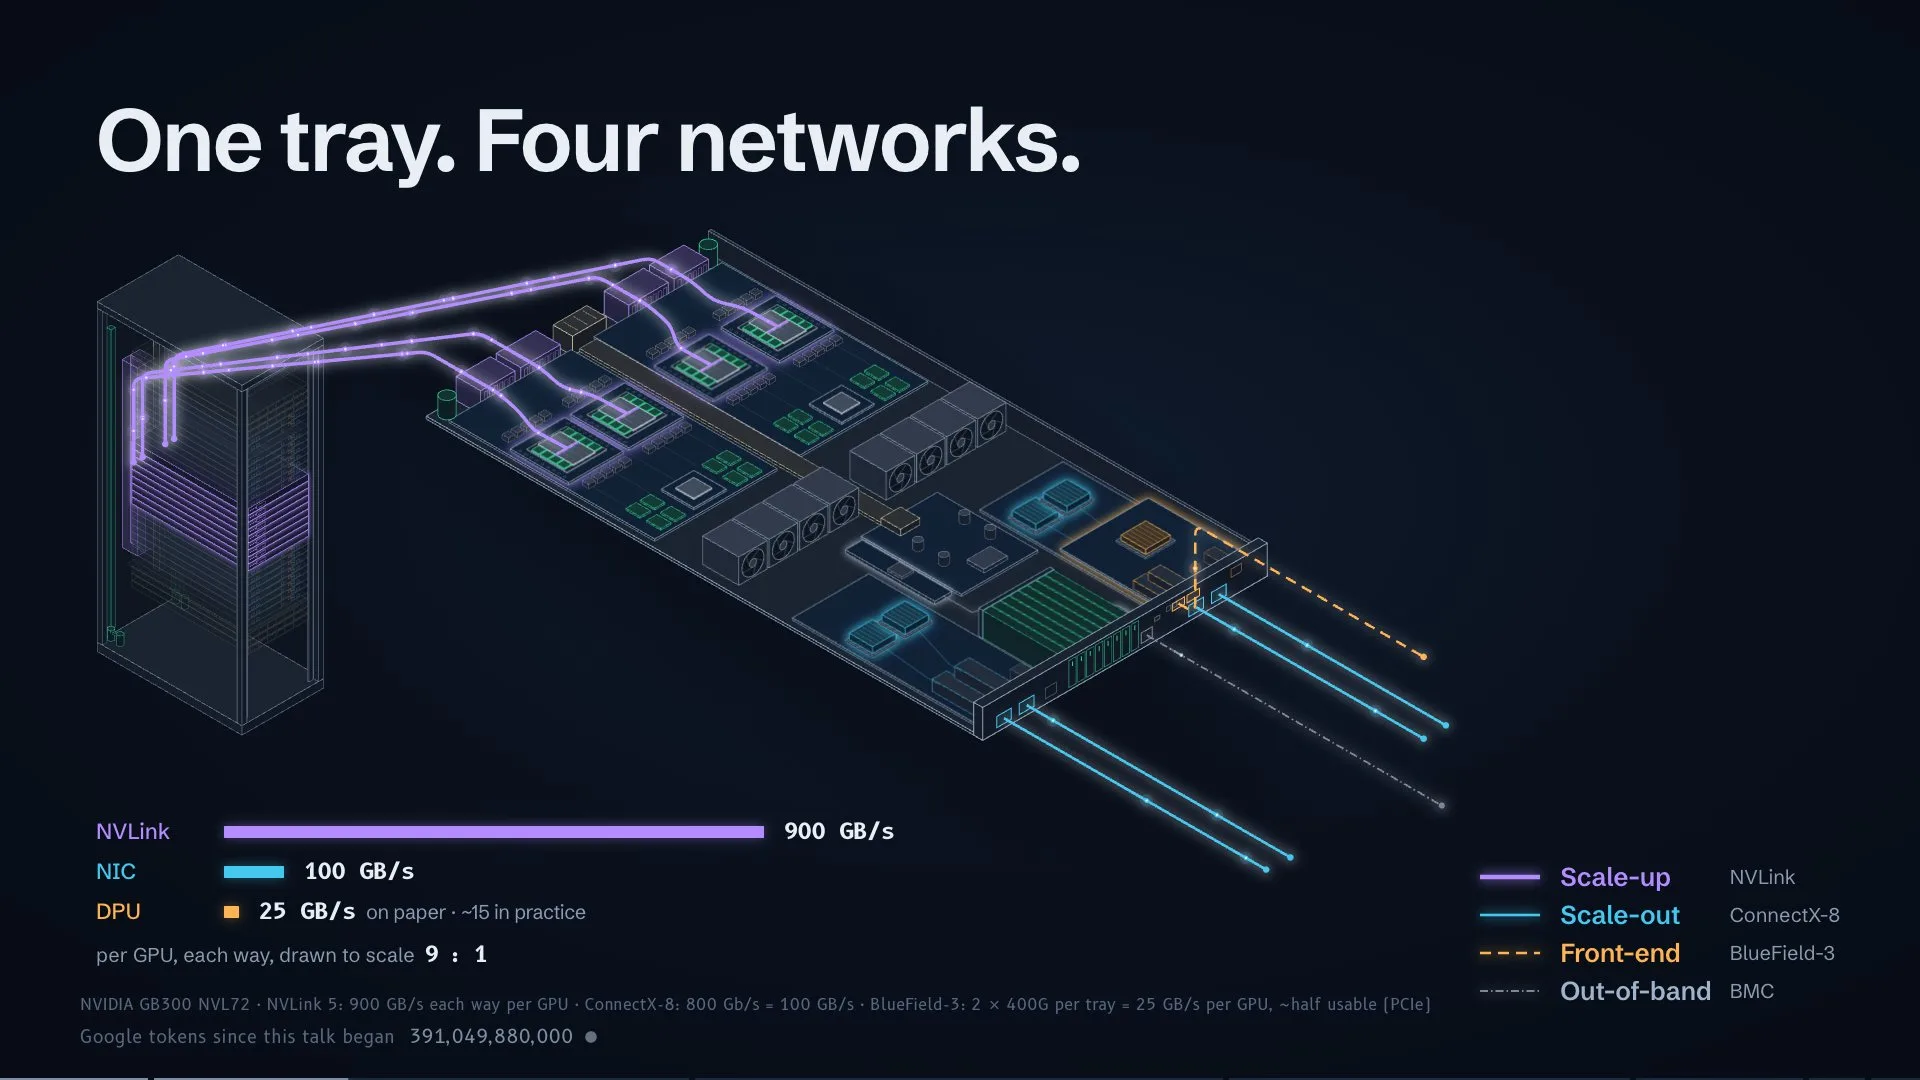
- One tray, four networks
- The rack is one computer
- Rails: the back-end
- Stay at two tiers
- Why AI traffic breaks networks
- Scale-across
- Same wire, different names
- The last centimetres
- If one nanosecond were one second
- Stay inside
- Every token costs a full read
- Does the model fit?
- A conversation has a footprint
- Hot, warm, cold
- Back from lunch
- Training vs inference
- 2022: one box was enough
- Think longer, remember more
- Split the work
- One rack, both phases
- Where does an agent run?
- Inference used to fit in a box
- Four networks, four jobs
- Light is the new copper
- The silicon zoo
- The answer arrives